

























New on LowEndTalk? Please Register and read our Community Rules.
All new Registrations are manually reviewed and approved, so a short delay after registration may occur before your account becomes active.
All new Registrations are manually reviewed and approved, so a short delay after registration may occur before your account becomes active.
GPT-6 Astra
New variant of GPT just spawned: GPT-6 Astra.
Anyone used it yet? Claims are bold: https://deploymentsafety.openai.com/gpt-6-astra
Tests seems to be somewhat missleading as per discussions in ycomb: https://news.ycombinator.com/item?id=49554643
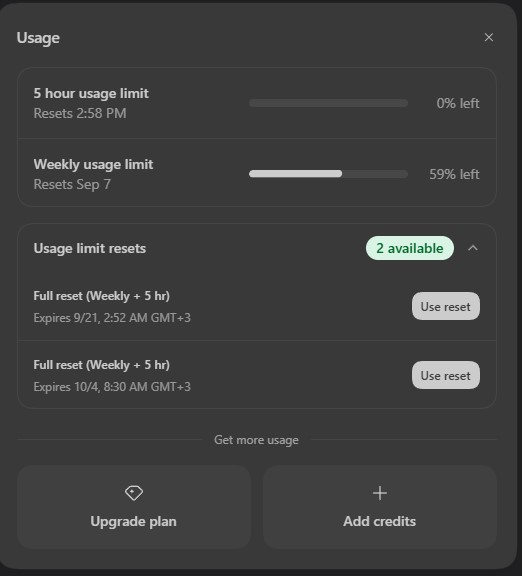
Side note: did you noticed that weekly resets are capped? Like this:



Comments
LOL.
i am not impressed at the current pricing and Gemini 3.8 Flash giving 2000 tok/s at literally 0$ input
i would say that yes its good, it's the reason my gpt 5.6 sol acting like a bum recently.
What are you all using them for? I see people so excited for each model coming out but what is the use-case? Are you all vibe coding some complex software I dont know about?
Reverse engineering BLOB?
Same reason sheep camp out in front of Apple stores. Commercialism and awe.
I would rather ask what you don't use it for?
fine-tune open-source projects for personal use cases, setup networking & infra, drain all the remaining tokens because my plan expires in 1 day
Frontier models? Not much due to guardrails.
But things like GML turn out to be opensource at times and that is useful again.
No offence, but all recent gemini models are shitty quality, even tho their benchmarks look like a miracle.
IDK why google keeps pushing -flash models instead of seriously working on a Fable/Astra/K3 rival for real. Gemini 3.1 Pro is also kinda shitty... full of "you're right, I missed that".
3.1 Pro is far behind, 3.8 Flash is ok because its so cheap, 3.6 Thinking in between ~
I plan to test it, but GPT, has disappointed me so many times that I just gave up after 5.5, and did a fast test on 5.6.
I will probably give the new one a try, but to me it seems that gpt has issues with context which results to bad results .
Fable has been good specially in following repetitive workflows and reports .
We use both mostly for repetive taks and QA of user interfaces, or data entry and chat gpt falses miserably on using browser etc
I'm happy with Sol + luna.
With the way that Sol has been eating up my usage lately, Astra is going to be a lot worse. Sol does what I need, so I don't see myself changing.
I'm pretty impressed by the reverse engineering of apps by AI. It's fixed a couple of stability issues the actual developer couldn't fix in over a decade. One developer I know said he was close to beating echostar ecm's with a basic GPU like 10 years ago, probably doable with a modern GPU and proper teardown of nagra protocol.
Been pretty happy with Sol already.
Pretty good only my 2nd session with GPT-6 Astra doing security audit review with Trusted Access For Cyber level 1 access enabled https://ai.georgeliu.com/p/openai-trusted-access-for-cybers with reduced safeguards for defensive security work https://www.threads.com/@george_sl_liu/post/Dc4iEuPExFE
The 72 million GPT-6 Astra tokens reported by ChatGPT Codex native OpenTelemetry exported usage metrics in Grafana represents 34% of my ChatGPT Pro $100 plan's weekly usage quota https://www.threads.com/@george_sl_liu/post/Dc4hkOLk_oRai
Big fan of gemini, use antigravity flash usage is great think it's coding skill is under sold, it's solid people just ain't using it right.
I get similar performance to Sonnet 4.6, opus 4.6 no complaints.
The biggest thing that burns tokens for me currently with GPT 5.6 is using AI to prototype and benchmark improvements in performance critical code.
Its easy to have an idea of how some change could be a better architecture, alot more painful when you need to spend days developing it and days testing it only to find out the idea is not a net positive.
I've found this to be far more useful than full vibe coded implementations as it:
a) serves a verification before actual man hours get spent
b) is a functional prototype that can be used as the base for an in-depth review / re-implementation
Zai is handing out 400m tokens for GLM 5.3 Flash in Zcode, so far seems not too bad
Even you sucumb to llm? Tafak Timbo.
Dont you love it when a reset comes with a token reduction?
#HonestTokensThey are trying so hard to milk users for every single penny.
It's online today. If you want to use it at a low discount, you can contact me
Huh?
"CYBER CYBER"
Sorry Dave but I can't do that.
You have been switched to Opus.
I had done optimization but with slight different pathway.
use chatgpt to connect the repo, audit the code. and then do a cpu profiling and then give the report to chat, and ask to plan for any remaining optimization. Implement the optimization with luna High or terra.
pre and post benchmark. one optimization at a time. if regressed, go back. Repeat.
yeah, same shit here. I even get downgraded to Sonnet at times. cyber punkssszzzzz
That sounds like as much work to implement as it would just be to do the work.