

























New on LowEndTalk? Please Register and read our Community Rules.
All new Registrations are manually reviewed and approved, so a short delay after registration may occur before your account becomes active.
All new Registrations are manually reviewed and approved, so a short delay after registration may occur before your account becomes active.



Comments
Pretty much, i dont bother with multi provider or harness either, i just plug shit into whatever IDE gives free credits at the time, else fall back to Gemini for paid/account, GLM for api/usage
Yes, some manual work is ofcourse but it worth for the results.
consumed 3b input tokens and 60m output tokens just 2 months
I use AI with a master brain (most of the time my self-hosted K3 or GLM5.2) and rarely Claude.
That brain is whipping the asses of all free-to-use LLM models. Have like ~50 that I can use at no cost at all... lol.
https://i.ibb.co/7xd4XVqQ/image.png
I support safe and productive AI. I use it at work all the time for processing data quickly and rewriting emails and documents because me rite no gud.
One of their largest use cases is as cheap as possible bulk inference flash for the top of search result page, google assistant, hey google, nest (since users expect this usage free)
The others companys don't have this use case or this customer base, for thing like google assistant or siri, you need LLM that answer as fast as possible while cheap, but google wants everything server sided to log the datas and apple wants fast models running local on iphone
I operate a token aggregation site that sells GPT tokens at a 50% discount
Nice. What methods do you use to obtain tokens?
We use official discounted prices in each region and every time to purchase subscription packages。
Do you use carded cc and stolen accounts?
I think my claude Opus 5 + my Gemini Pro (Free) is enough for me.
I wanted to try Fable but leave it for now
This is illegal, we use reasonable discounts
I think they would prefer more information given openai does not really do discounts or regional pricing outside of Go
He is saving tokens
Yes, but OpenAI will provide some promotional activities for special groups
Meta has a similar use case but fails to use it thinking they are a coding outlet as does Apple but no real AI offer in Siri/iOS yet, Meta same as Google also offers inference basically for free.
Gemini 3.8 Flash is IN 0.00$ and produces 2000 tok/s of not even entirely garbage for primarily the search results, it also runs on Google TPUs and not Nvidia cards which is nice to rely not on single source (Gemini = Google TPUs, Zai = Huawei, ChatGPT etc. = Nvidia, AWS = Amazon)
I do 1-2b per day
That's not the flex you think it is.
Token cache likely included.
drinking a lake per hour but yeah the website was beautiful
Can we at least not act like we don't know how water cooling loops work? The permeation isn't that extreme
Youd be right if they would be using loops and often not just evaporation cooling, my work DC uses fresh water to cool the HVAC radiators because water is flat few while power is metered
You will understand when you optimize for microseconds. especially when you work with libraries like simd json. I had ported this library to C# for a parsing project and the optimization you are doing will be for nano seconds and microseconds. That to match the C# implementation with native C++. i was close.
Using AI for performance prototyping and CPU profiling iteration is definitely a smart workflow, though sometimes managing token quotas feels like playing a survival game. Thanks for sharing the insights
150mil GLM 5.3/Flash, Hy3, Deepseek tokens: https://kiraai.vn/dashboard/
No daily limit it seems, no payment info, i used some trash google accounts
Shit that would fly so fast... and I bet those are total tokens, not only input.
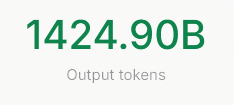
https://i.ibb.co/rGNfj2qb/image.png
Astra is goat tier
Bash me, but I like GPT-5.6-Sol more.
(if we stick to GPT family; else K3 FTW!)
You have been bashed sir, Sol is also prem, but Astra is premer
Wait until you use the Pro variant of the model. Your usage window is dropping like 50% per minute. LOL.